Survey Builder · Healthcare SaaS · AI exploration
Redesigning complex survey creation for speed, clarity, and AI-assisted workflows
Simplifying clinical survey logic first, then exploring safe automation for questionnaire generation
The Survey Builder is how researchers at Pulse Infoframe collect clinical data. Configuring a single 15-question survey took over ten minutes, skip-logic errors reached live studies, and two of five coordinators avoided conditional logic entirely rather than risk getting it wrong — which meant the data being collected was shaped by what the tool made safe, not by what the study needed.
The obvious move was to add AI. I didn't. I fixed the underlying workflow first, shipped it, measured it, and only then looked for where AI could remove manual work without removing researcher control.
Approached with Lean UX
Overview
Lean UX fit this because the work was two build-measure-learn cycles rather than one linear project: fix the foundation and prove it with users, then run an AI experiment on top of a base that was finally stable enough to justify one.
Discovery
Three problems accounted for most of the friction
I ran a heuristic evaluation against Nielsen Norman's ten usability heuristics, audited load time and latency with engineers, and interviewed five coordinators and three clinical researchers. Eight of ten heuristics were violated at severity 2–4 — but treating all ten as equal would have produced a list, not a direction. Three of them explained most of the observed friction, and those are the three the redesign was built around.
Poor system feedback
No visible save state, no validation until publish, no indication that anything had been accepted. Users re-checked their own work constantly because the tool told them nothing.
Hidden logic relationships
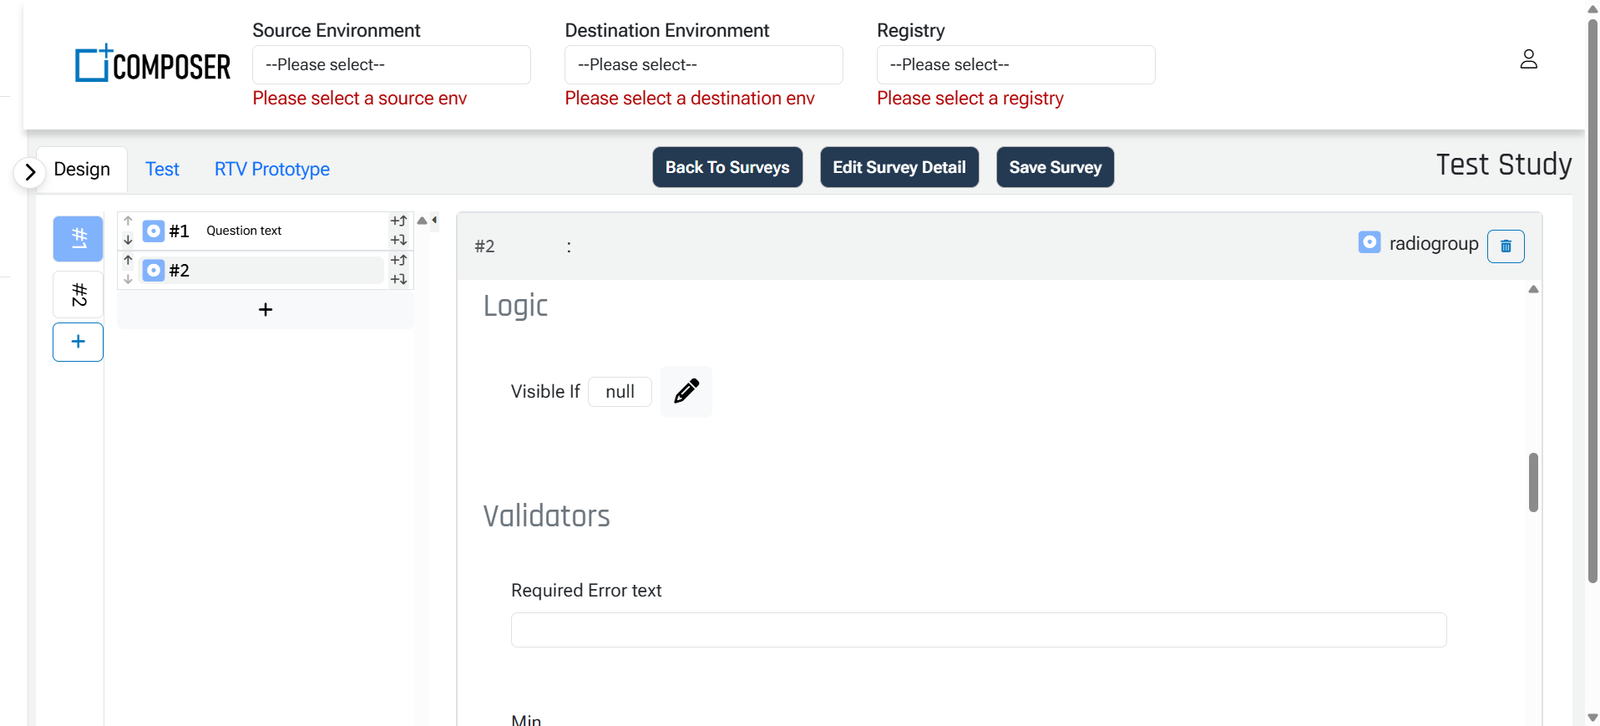
Conditional branches existed only as abstract “logic nodes” with no way to see how questions connected. Errors surfaced after publishing, in live studies.
Repetitive configuration
No templates, no bulk import, no reuse across studies. Coordinators rebuilt near-identical questionnaires by hand, every time.
Design reasoning
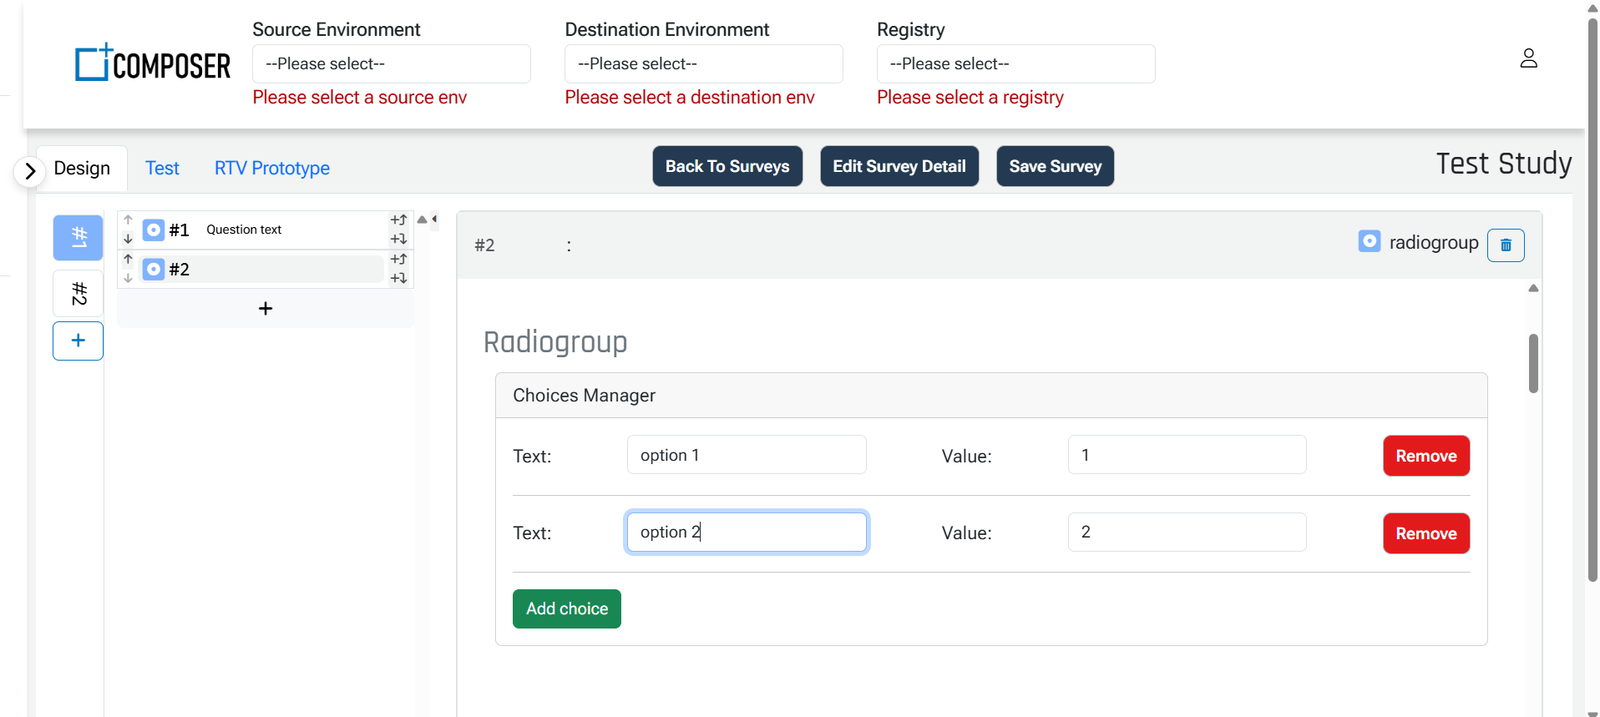
Before and after, problem by problem
The guiding hypothesis was that AI would only be worth adding once the builder underneath it was stable, fast, and predictable — an assistant on top of an unreliable tool just moves the errors around. Each of the three problems resolved into one structural decision.
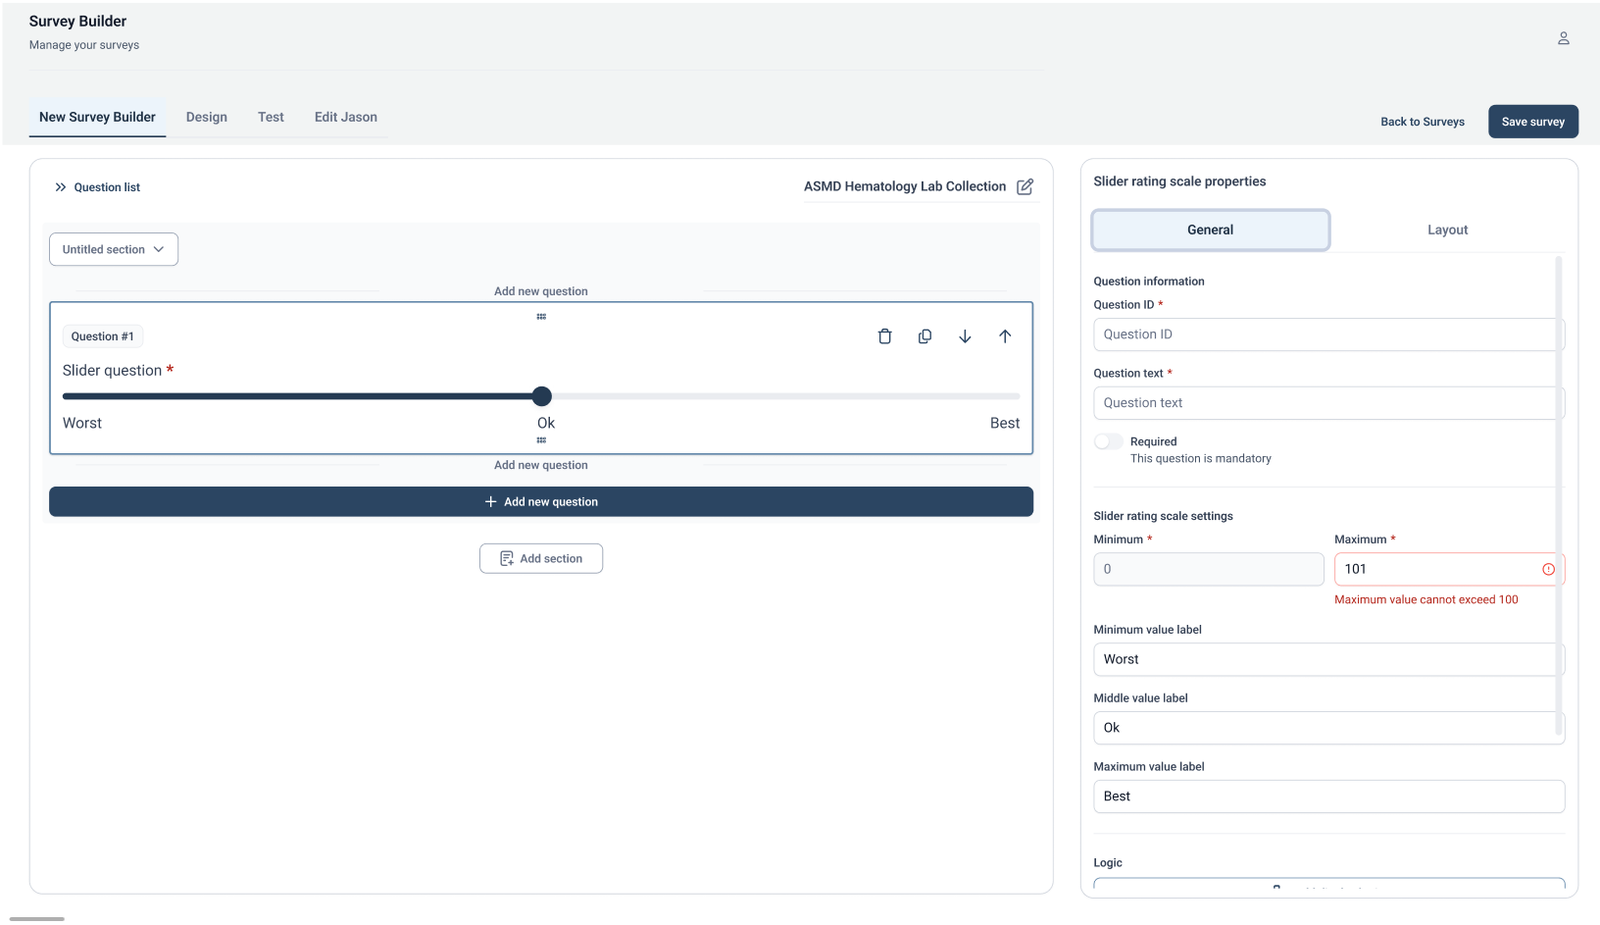
Poor system feedback
Nothing confirmed a change had been saved or a field was valid, so users worked defensively and slowly.
Immediate feedback and saved states
Inline validation at the point of entry, explicit saved-state indicators, and errors that describe the fix rather than the failure.
Hidden logic relationships
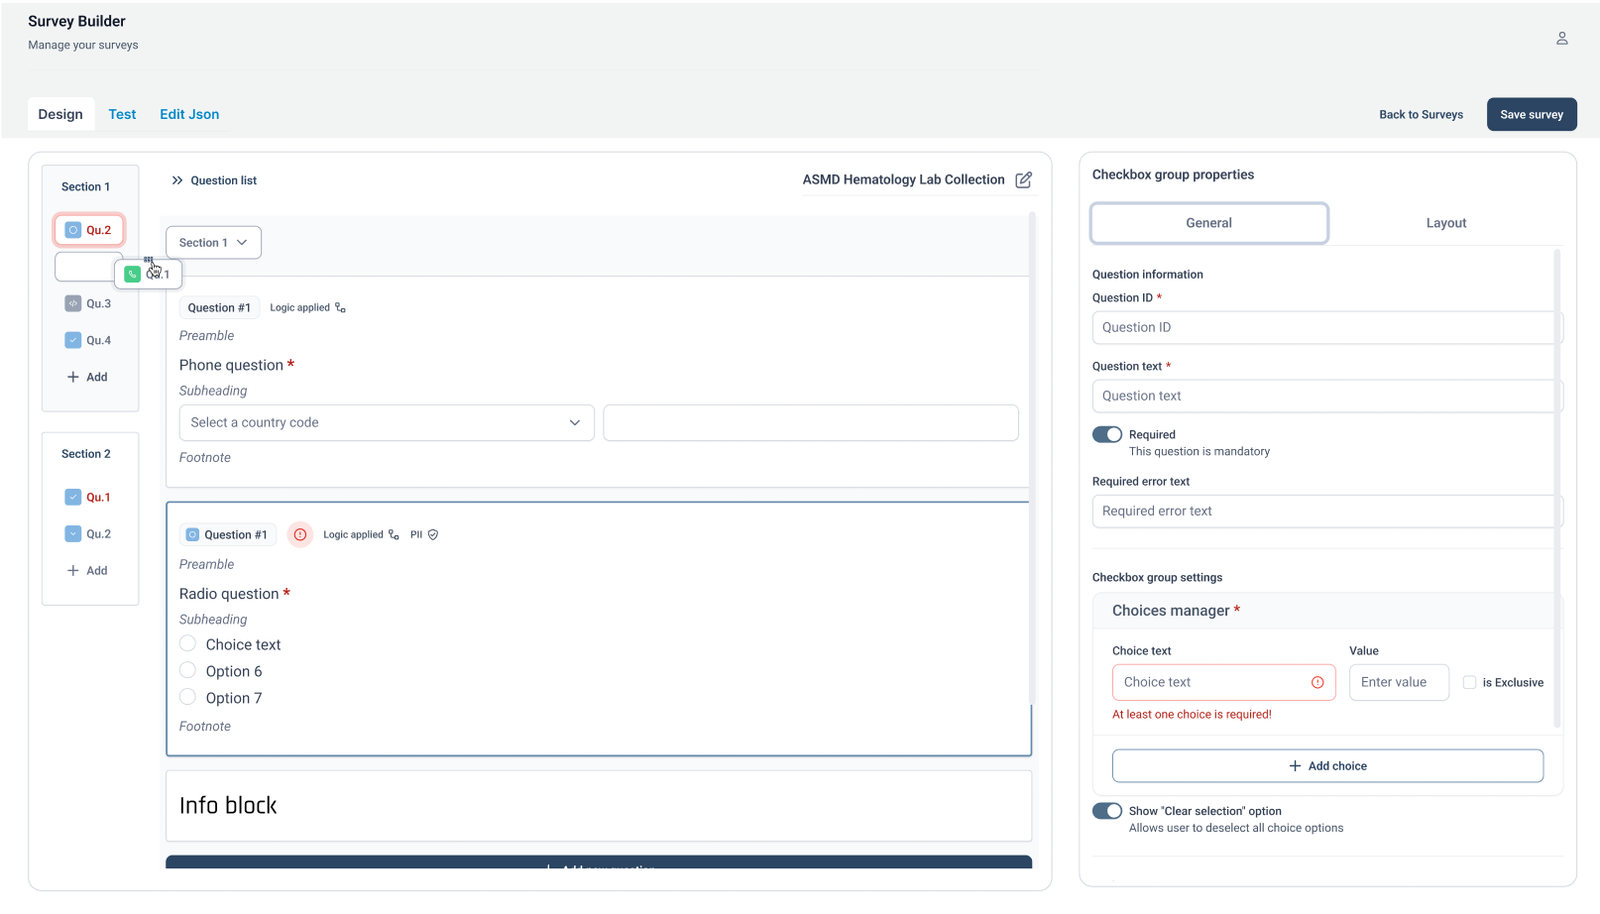
Conditional logic was invisible while being built and only testable after publishing to a live study.
Persistent, visible logic
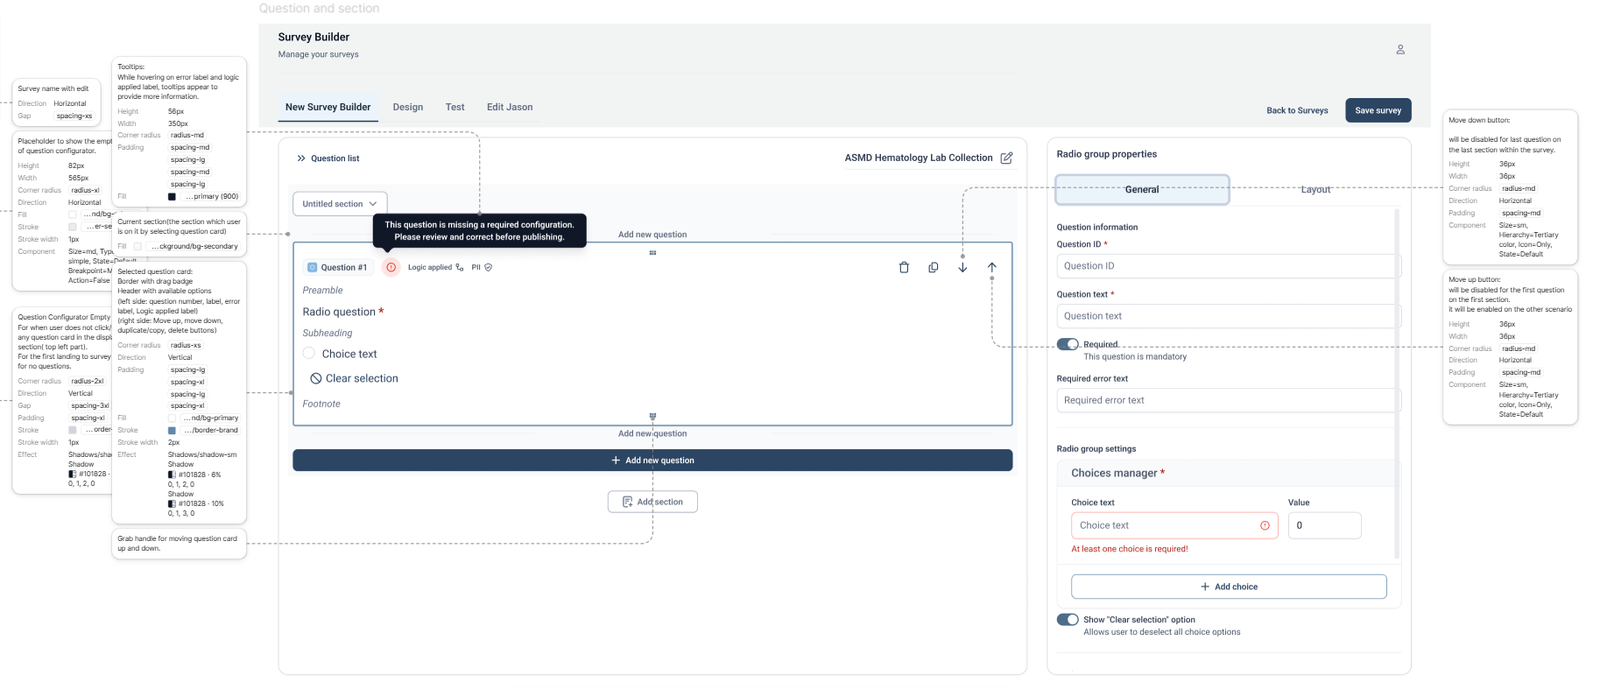
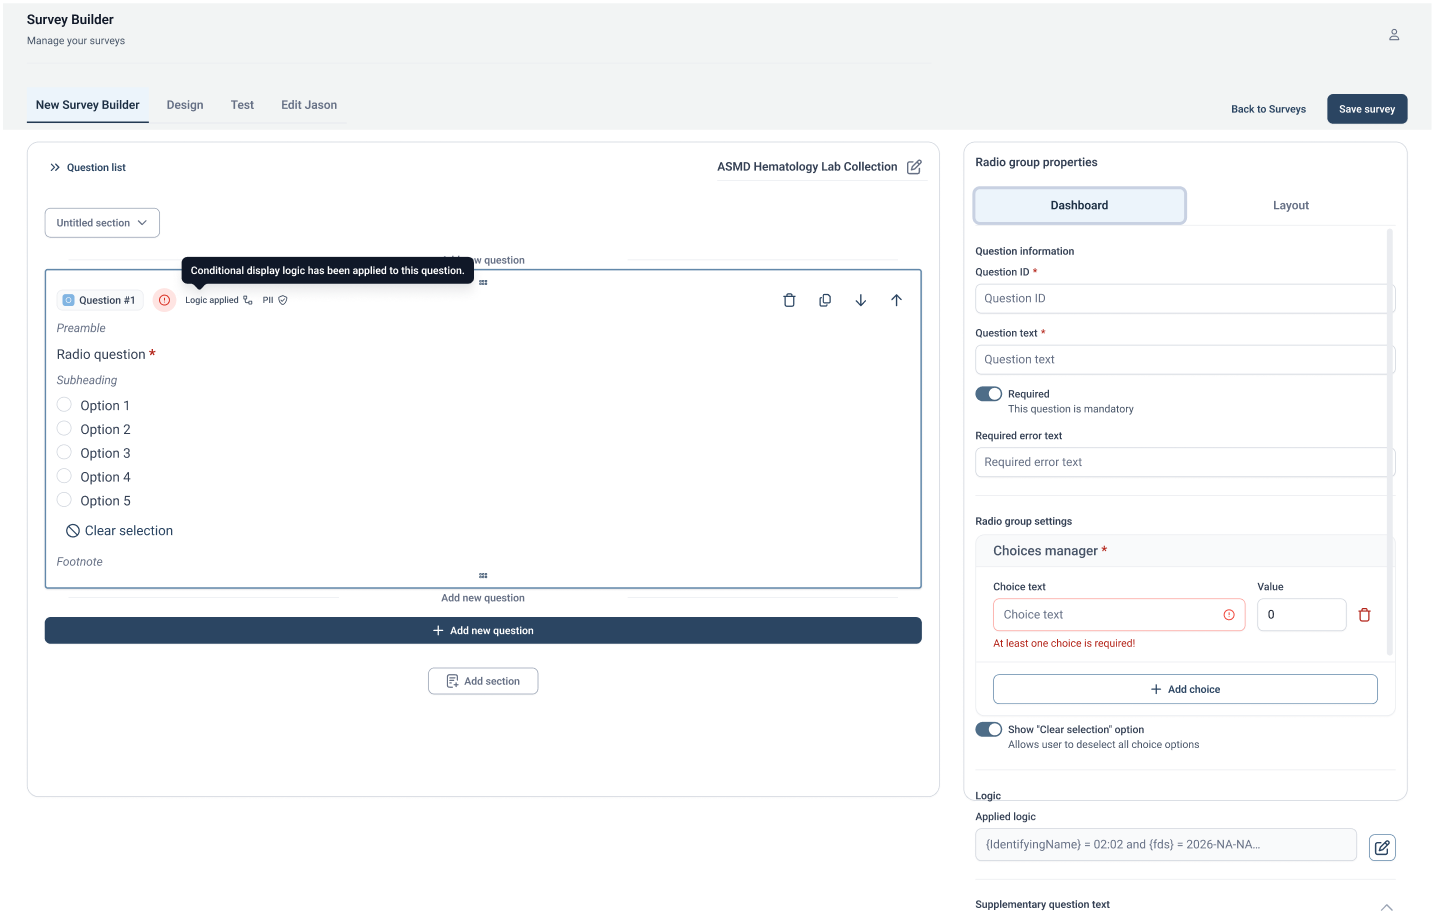
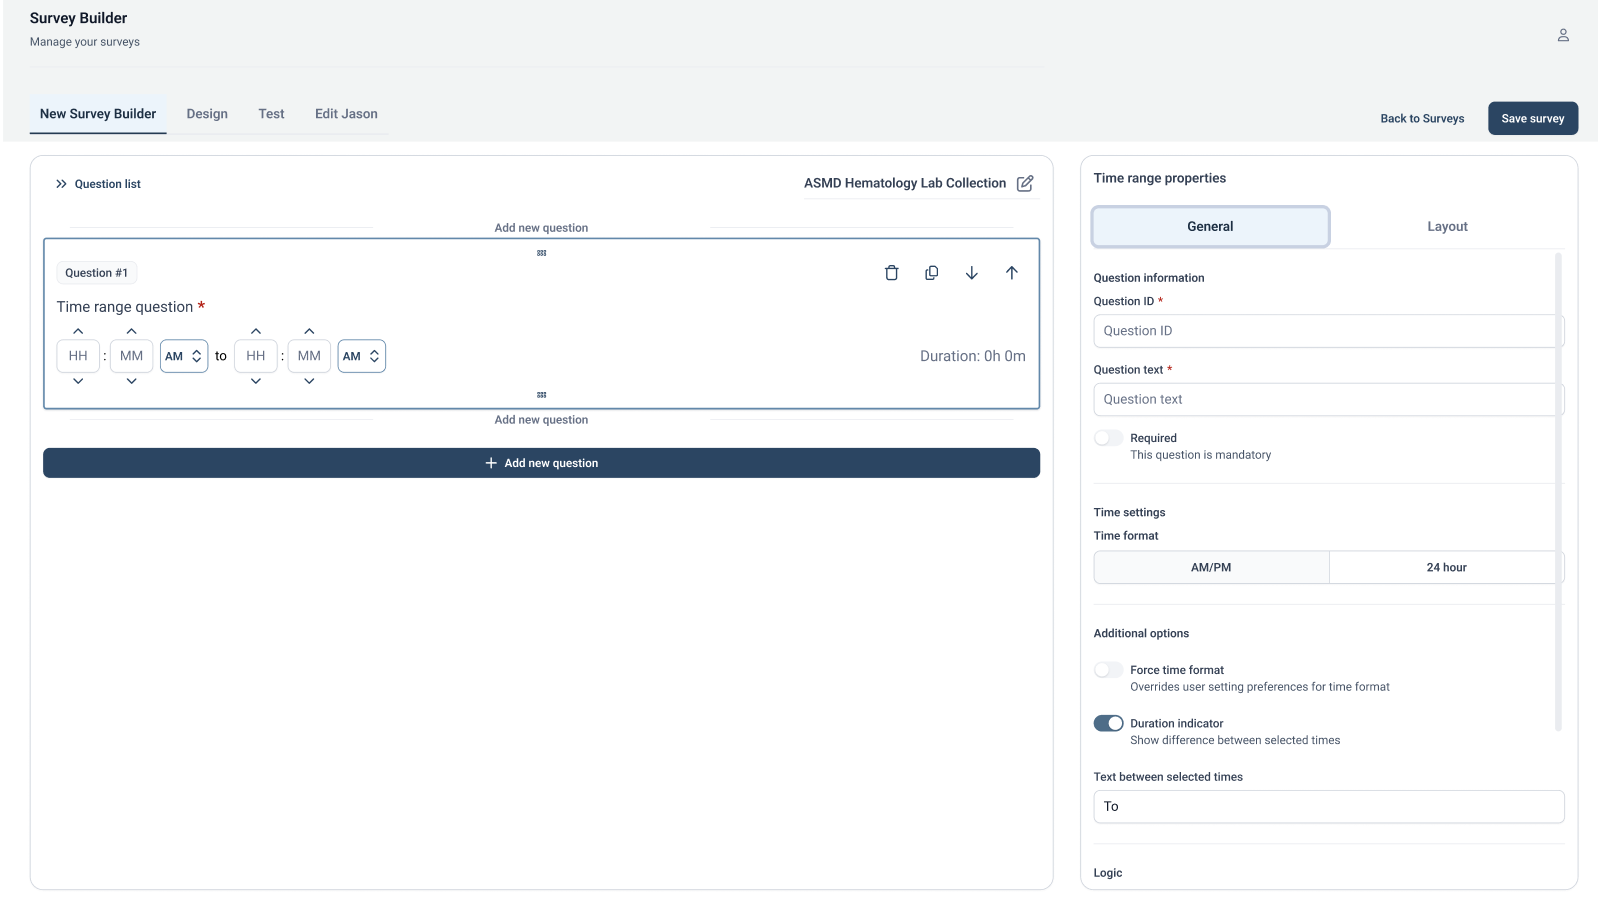
A left-panel preview that keeps the question hierarchy and its branching visible while editing, so a broken path is caught before it ships.
Repetitive configuration
Experienced coordinators re-entered near-identical question sets one field at a time.
Bulk entry and reuse
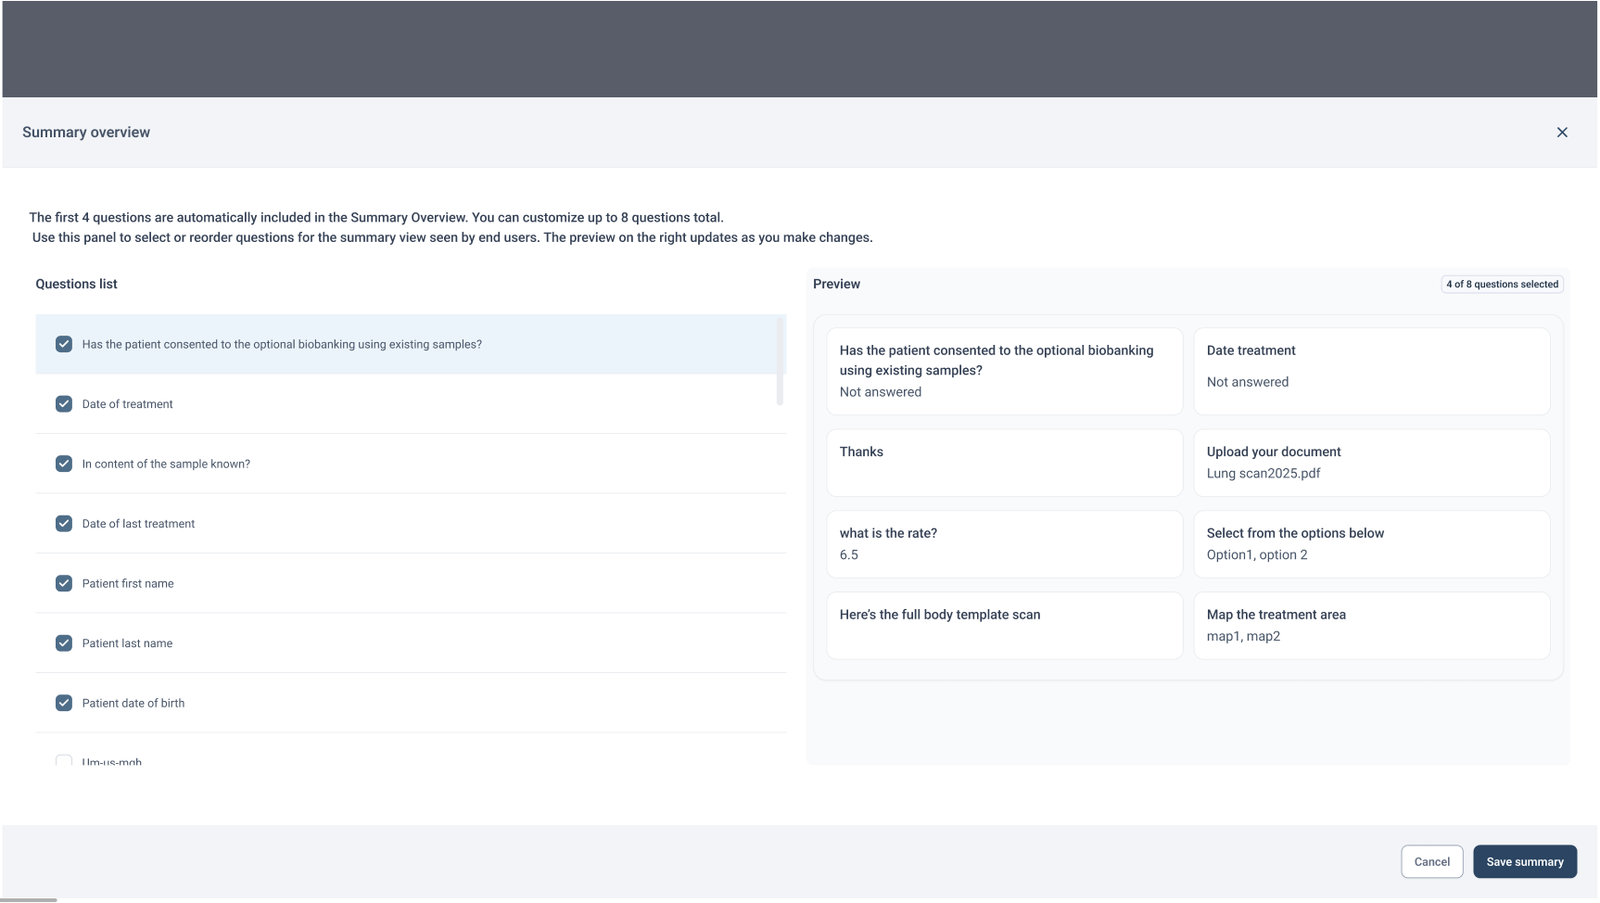
Bulk question upload and modular building blocks, so repeated structure is imported rather than retyped.
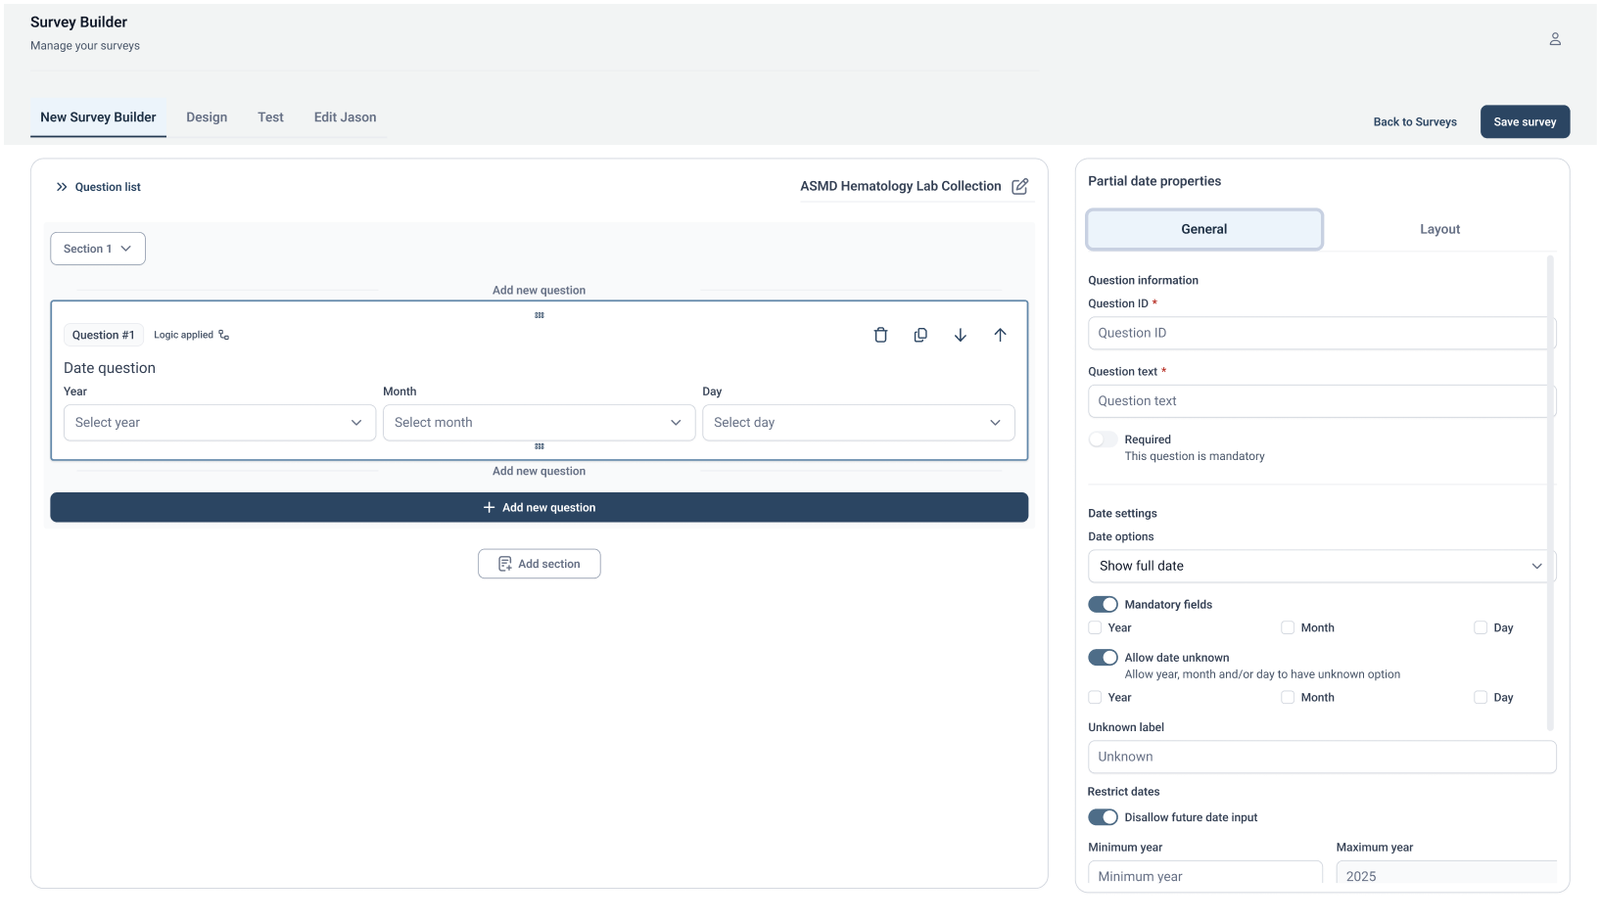
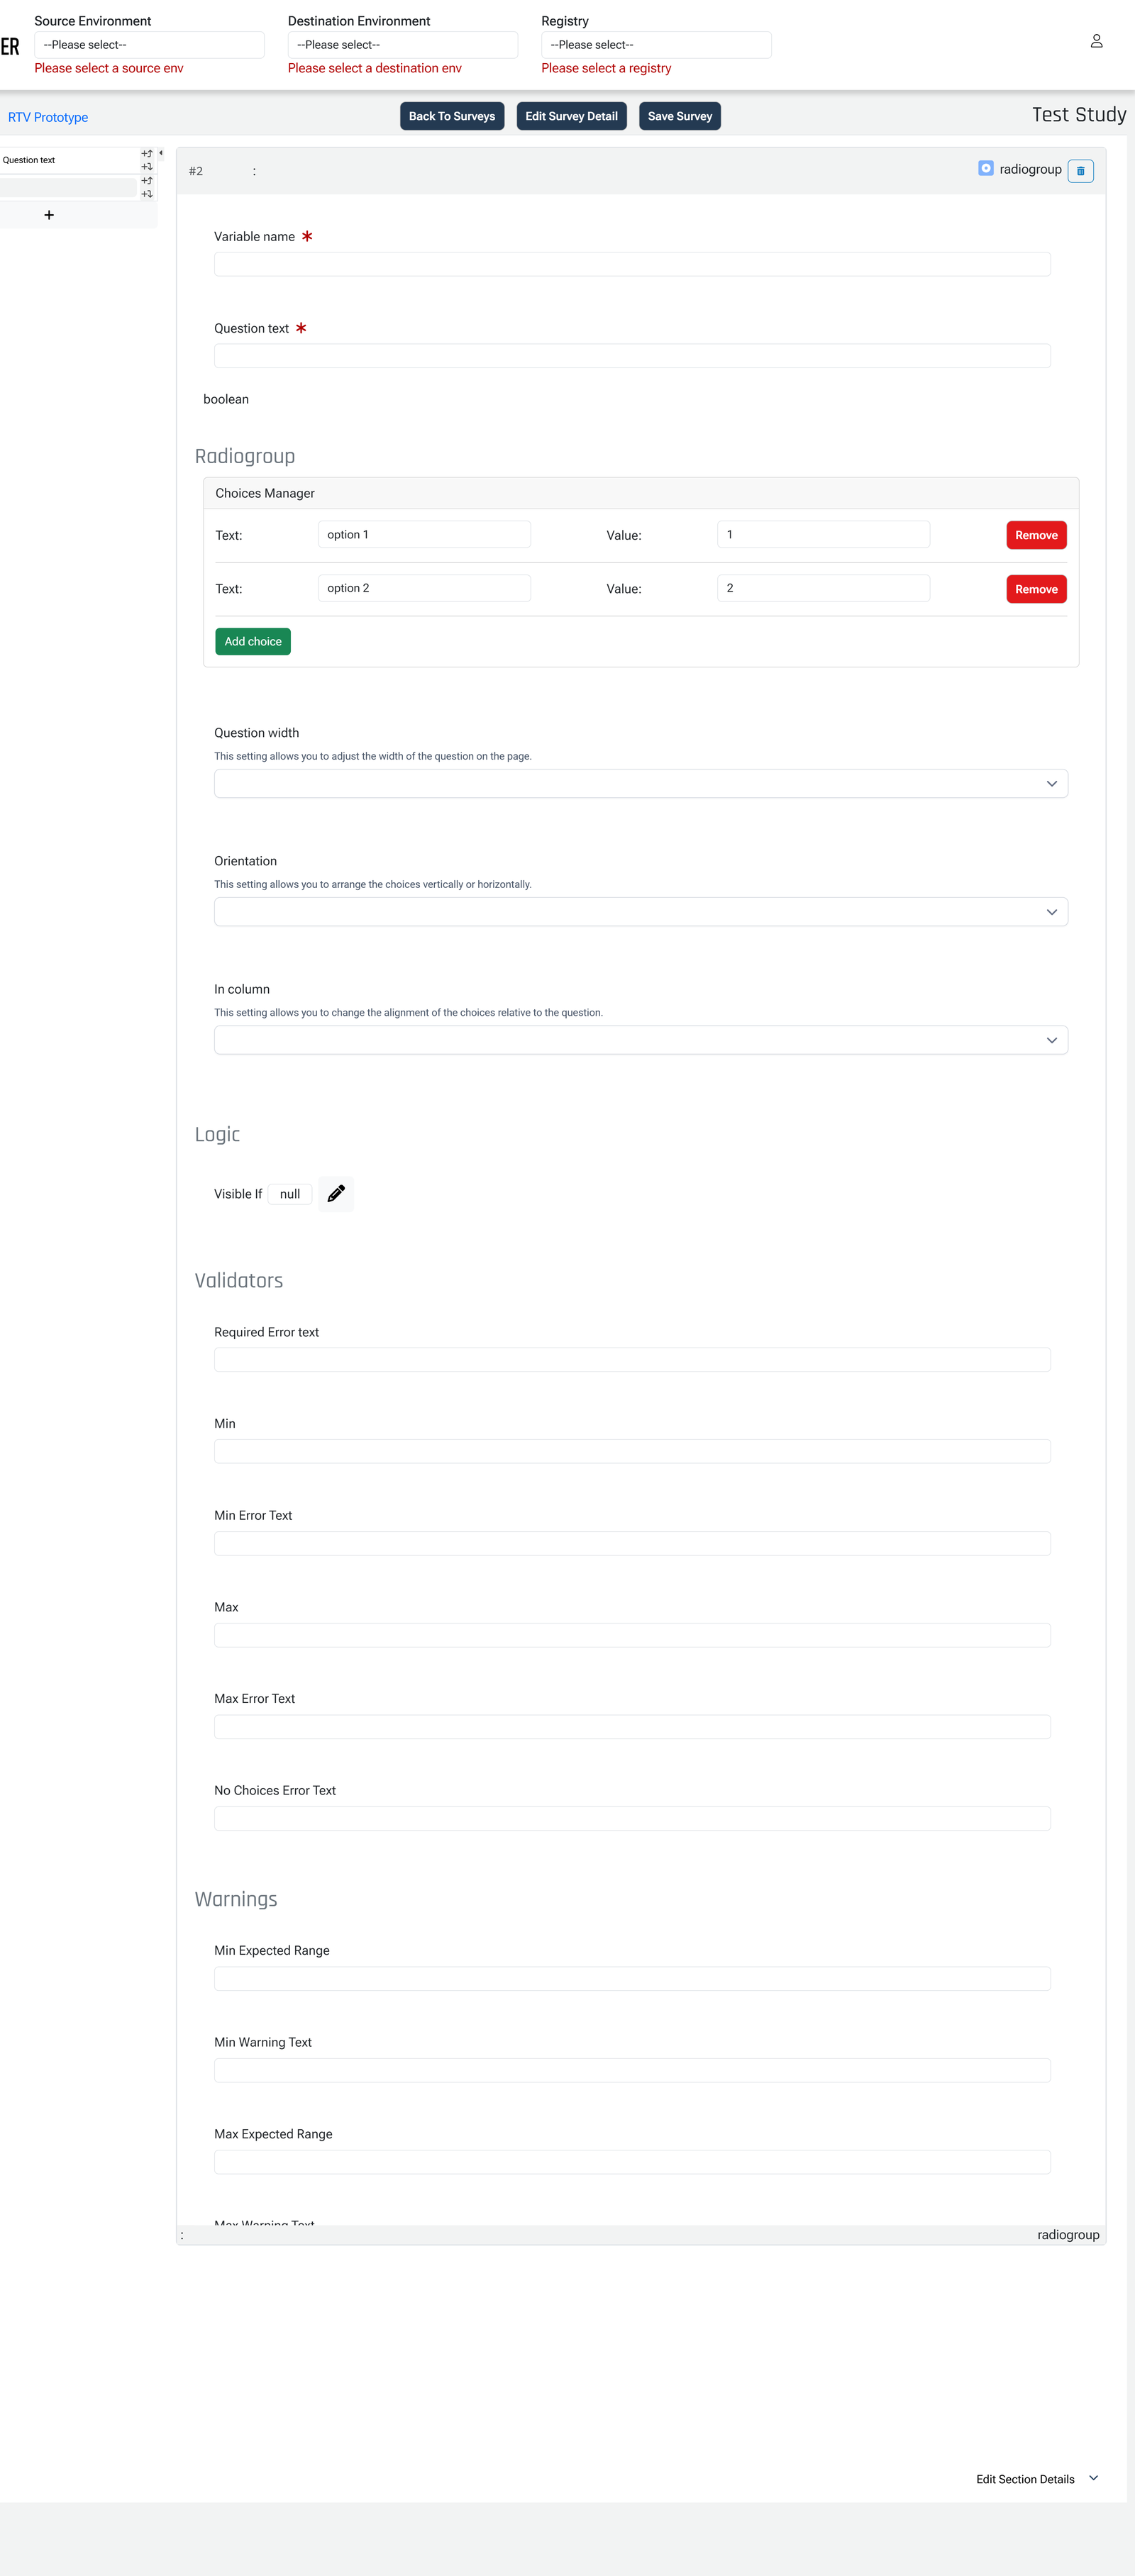
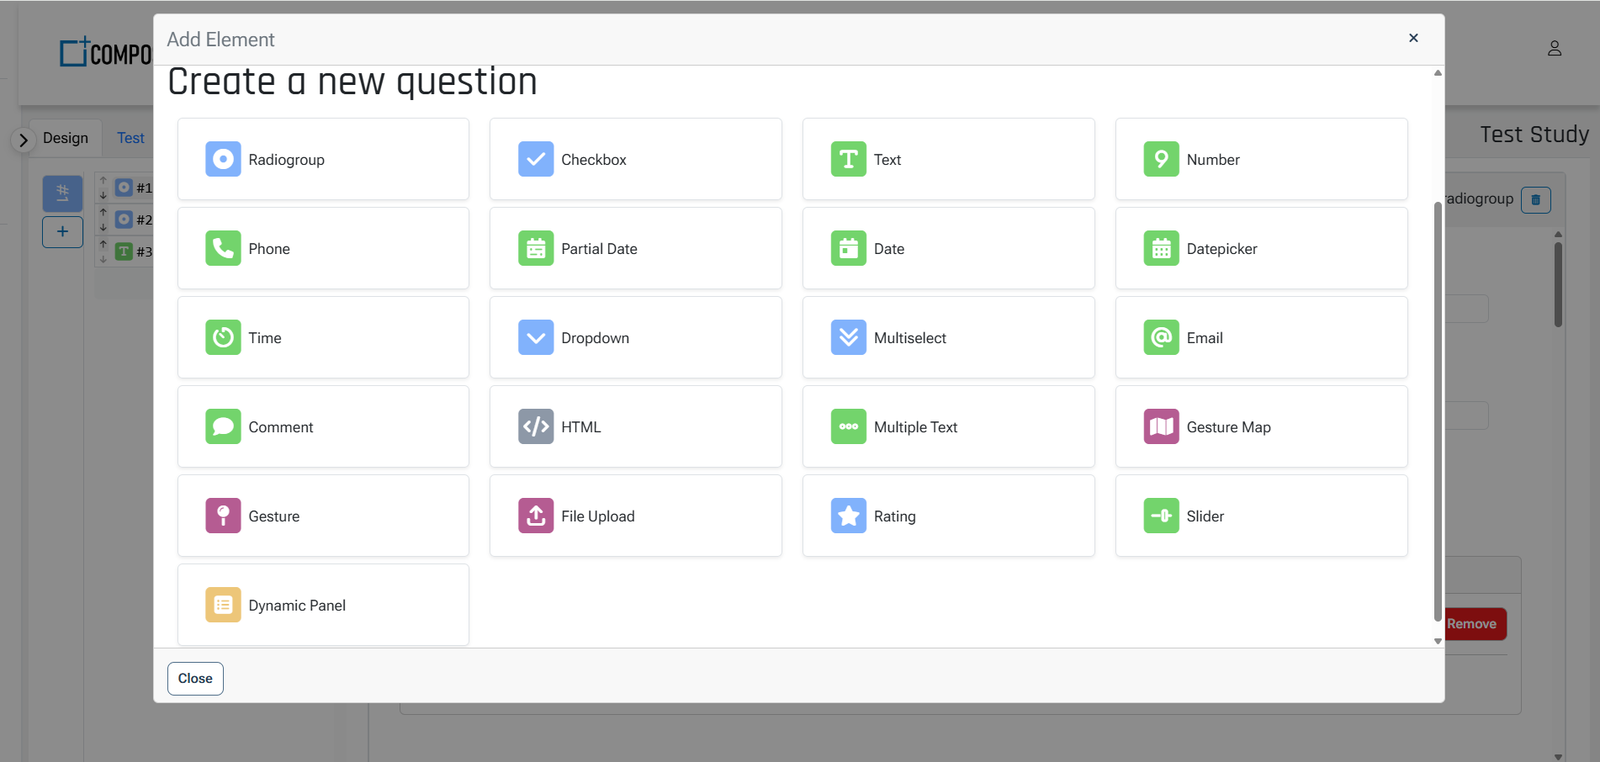
Before and after, side by side: the legacy builder offered a single dense surface with no hierarchy and no feedback; the redesign holds structure, logic, and status visible at the same time.
Shipped redesign
A performance-first survey builder
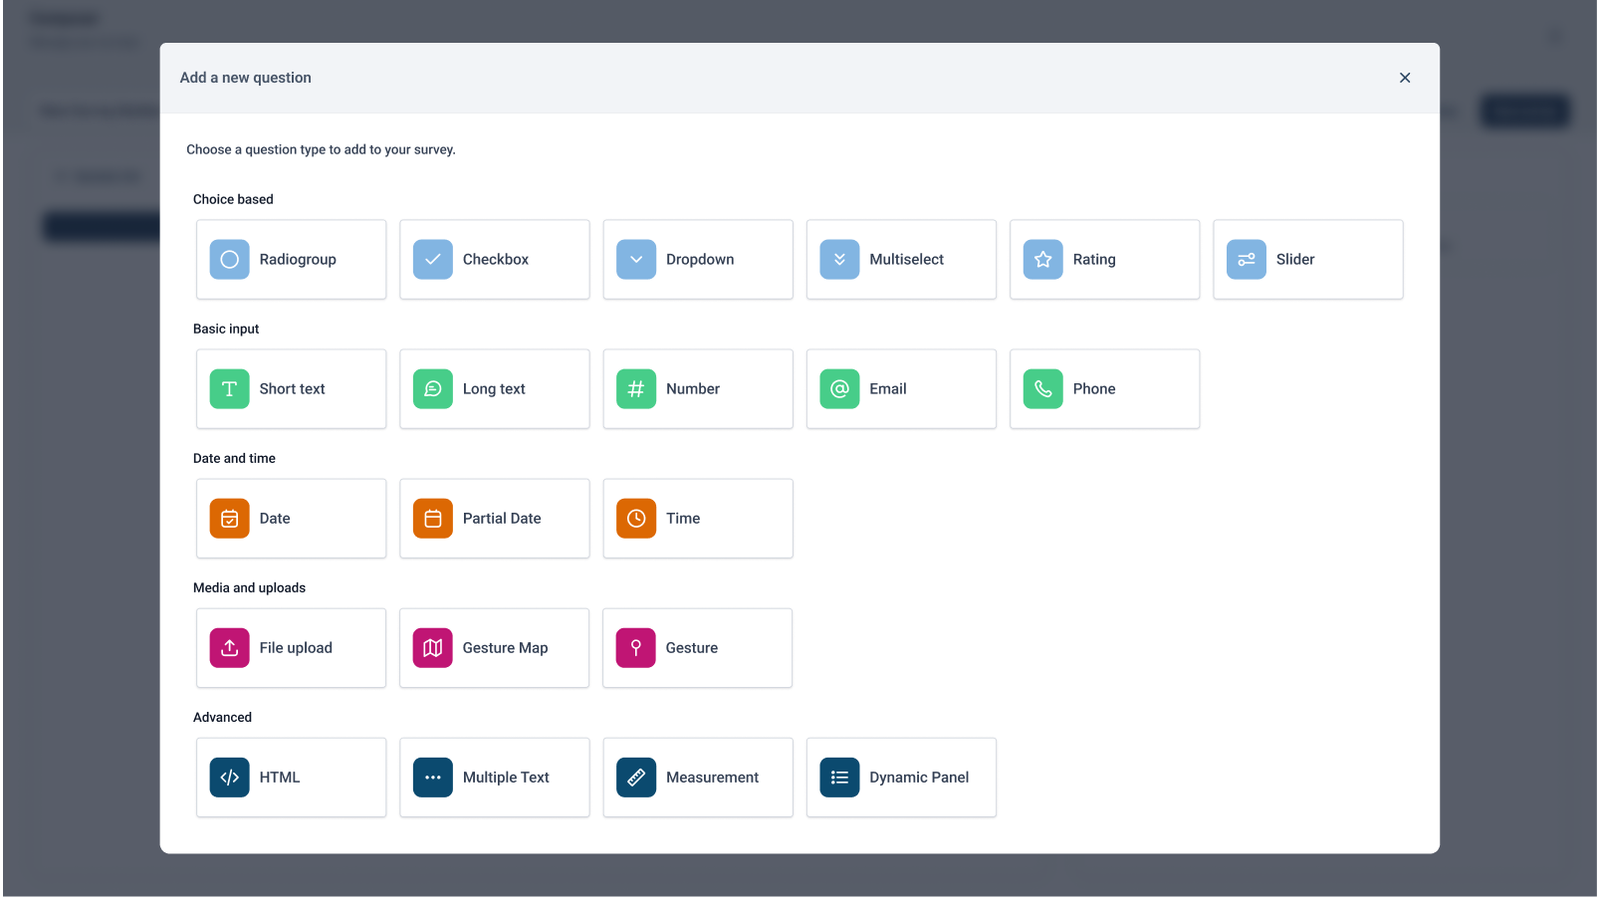
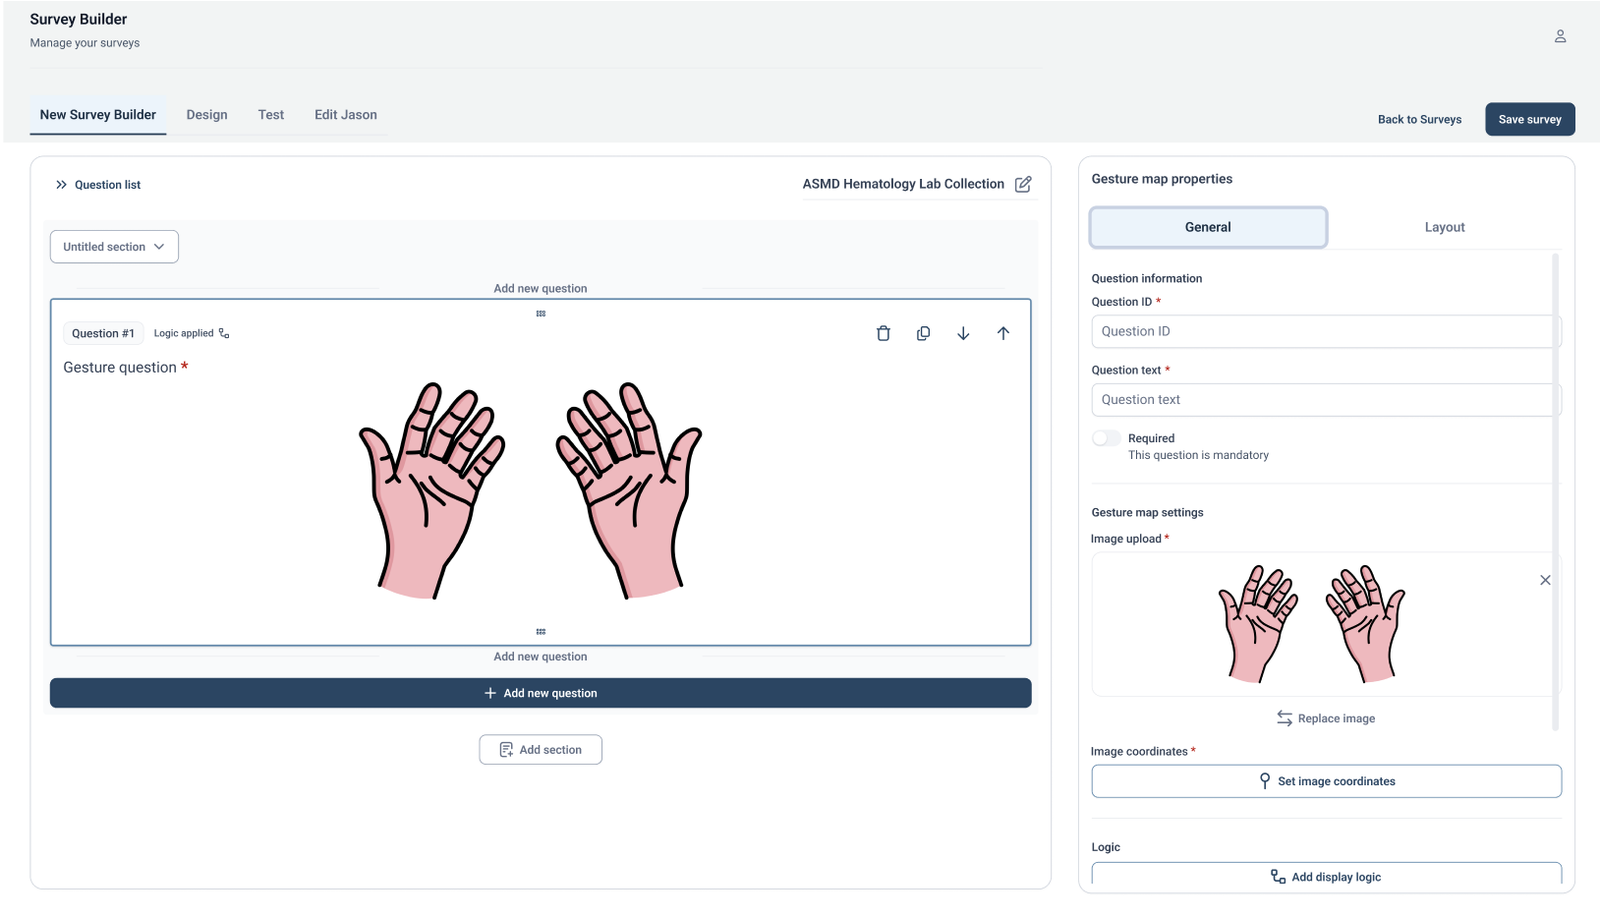
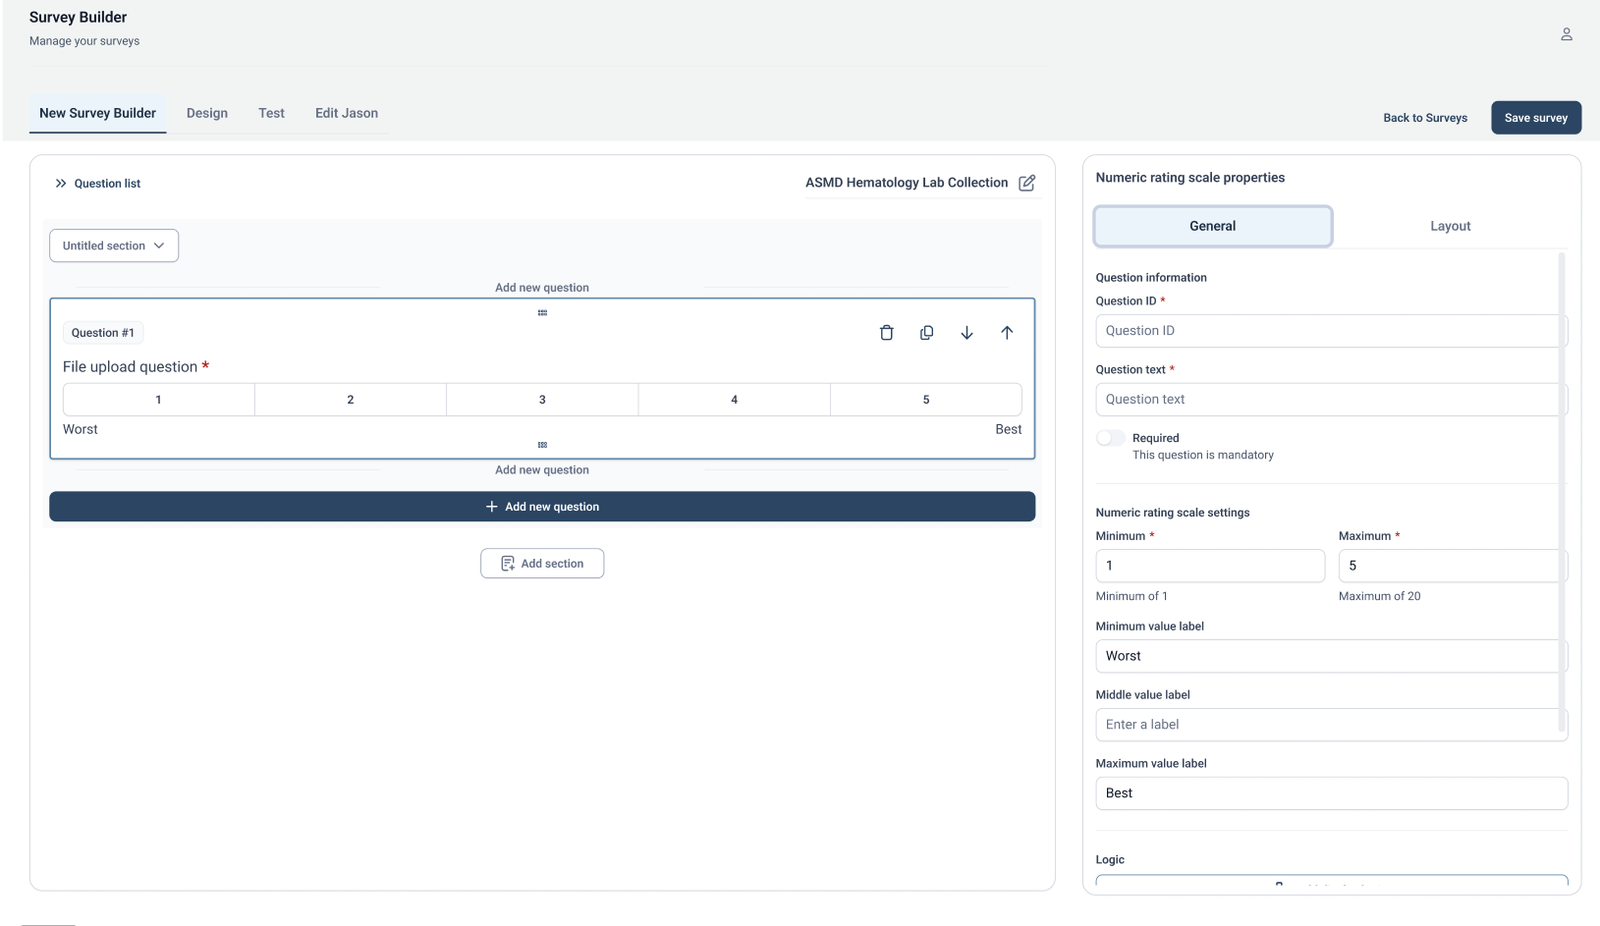
Usability audit → redesigned wireframes → new Figma component library → redefined information architecture → interactive prototypes → performance work with the dev team. The shipped redesign added a left-panel logic preview, click-to-edit fields with contextual help, saved states and validation errors, and bulk question upload.
Validation
What testing showed
Low-fidelity interactive prototypes tested with 5 users, followed by performance work with engineering. Participants singled out the preview logic flow and the modular builder layout.
AI opportunity
What if researchers could start with a validated questionnaire instead of rebuilding it manually?
With the core builder redesigned, I looked at where the remaining manual work actually sat — and it was upstream of the builder entirely. Researchers usually begin with a questionnaire that already exists as a PDF, Word file, or spreadsheet, then interpret its questions, response types, sections, and branching by hand before configuring all of it again.
The opportunity wasn't to have AI design surveys independently. It was to have AI transform an existing questionnaire into a structured draft, while researchers stay responsible for approving the final configuration. That shifts the concept from “AI generates a survey” to “AI prepares a structured draft that researchers validate” — a much smaller claim, and a much more defensible one in a clinical setting.
Document interpretation
Identify sections, questions, instructions, and response options inside an unstructured file.
Question classification
Map content to supported types — single-select, multi-select, free text, date, scale.
Logic detection
Recognize skip logic, dependencies, and conditional questions written as prose.
Structure generation
Organize extracted content into sections and reusable survey components.
Validation
Flag missing response options, duplicated questions, and conflicting logic before import.
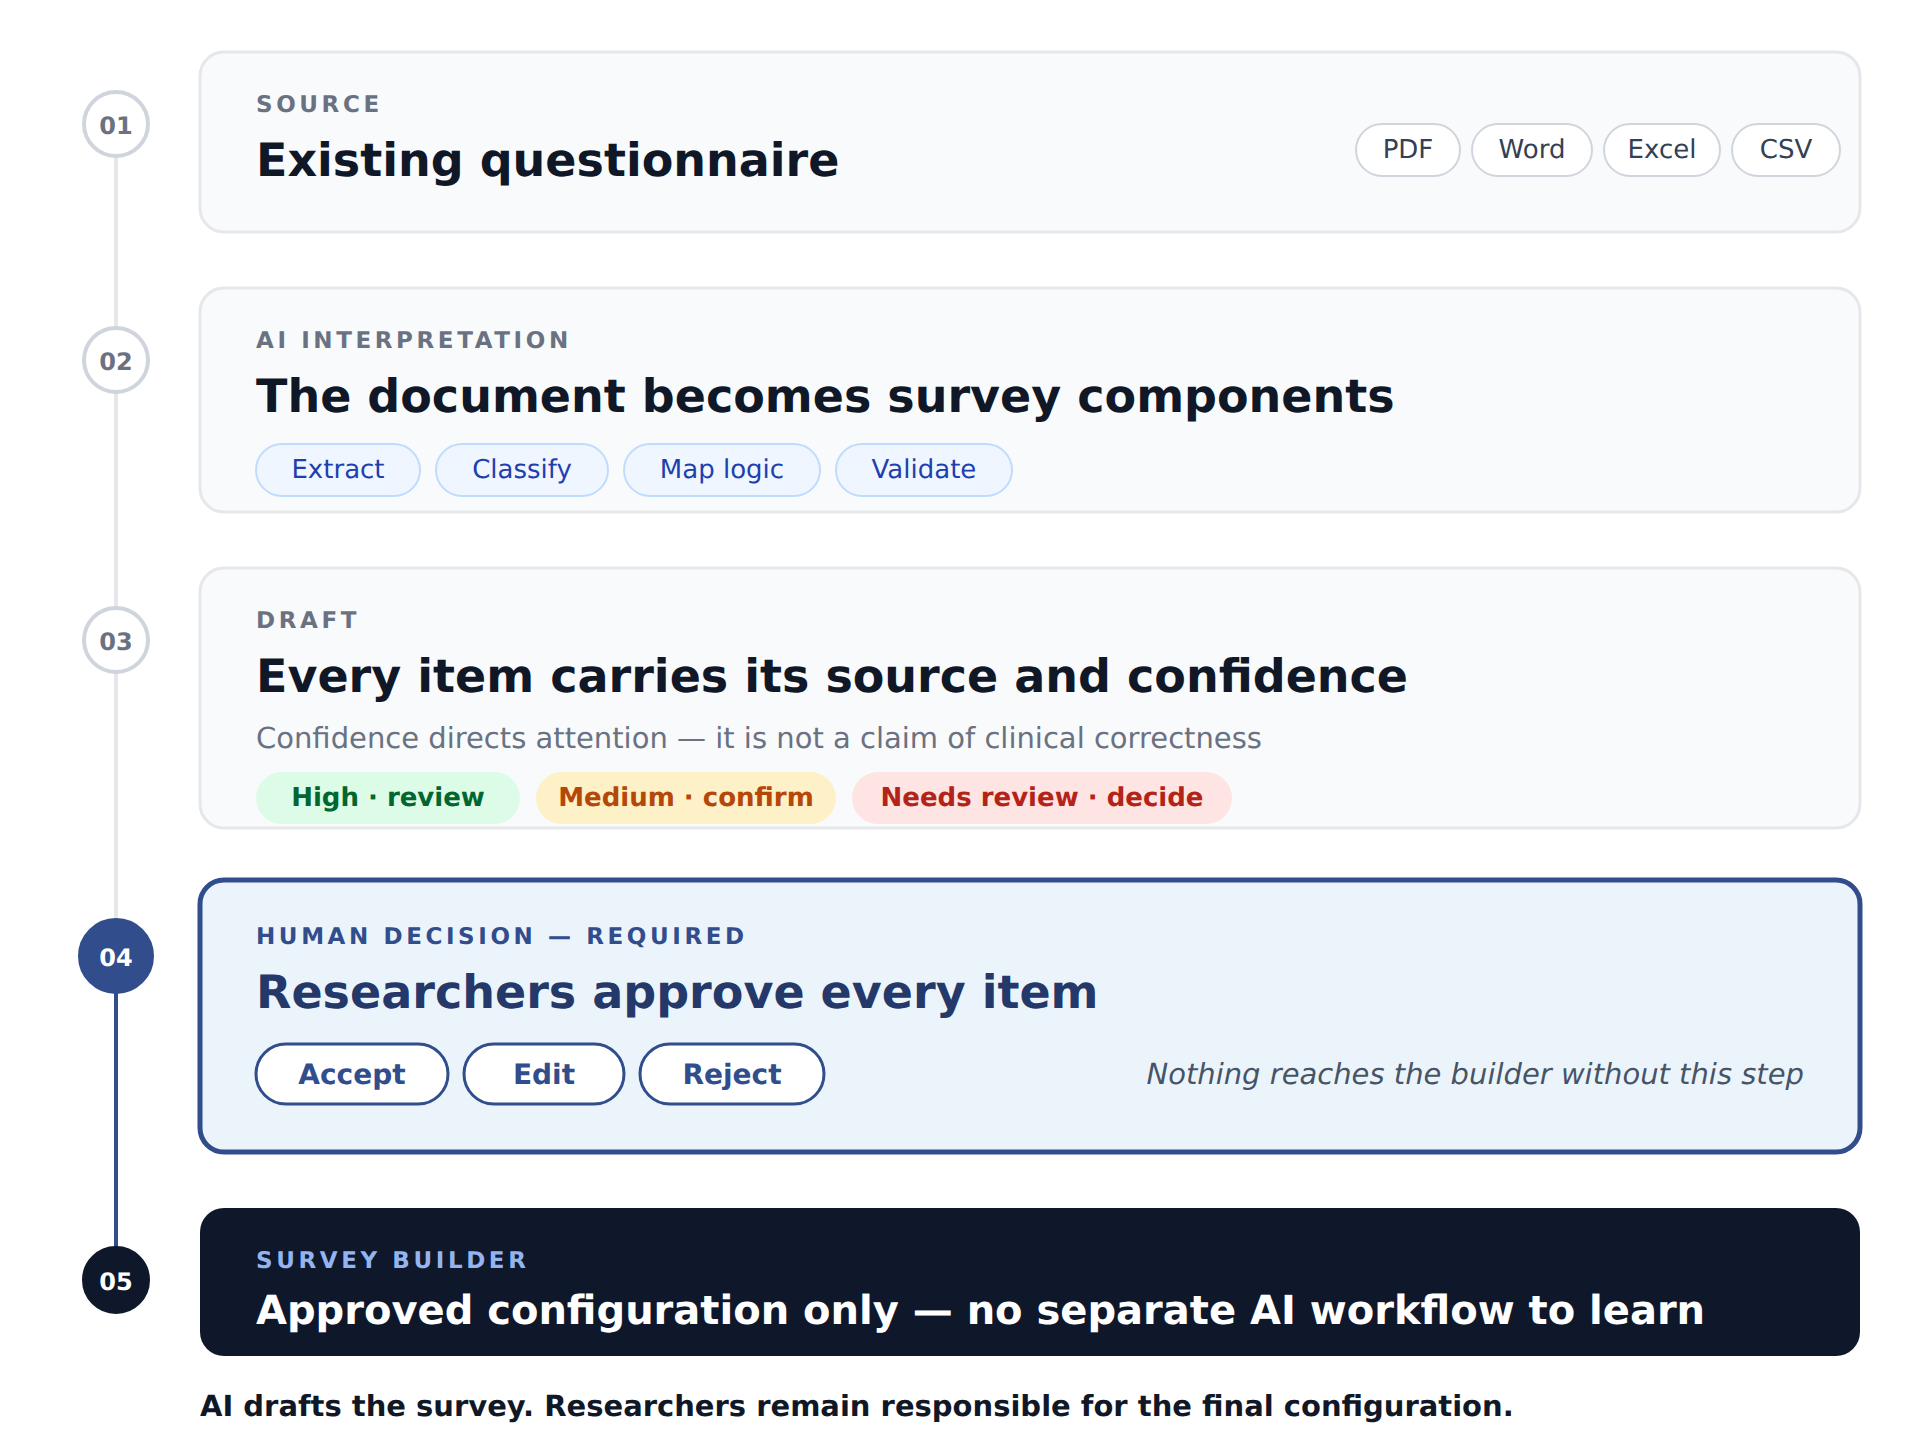
The mapping is what makes this useful at the product-model level rather than as document summarization: “Select one” becomes Single choice, a 1–5 response scale becomes Rating, “If No, skip to Q12” becomes conditional logic, and a section heading becomes a survey section.
Human-in-the-loop review
AI drafts the survey. Researchers remain responsible for the final configuration.
This is the centre of the concept, not a caveat attached to the end of it. Nothing reaches the production builder without review. Each proposed item exposes what AI detected, how it would appear in the builder, where it came from in the source document, how confidently it was interpreted, and an explicit Accept, Edit, or Reject.
Confidence is used to direct attention, never as proof of clinical correctness. High confidence means a clean match to an existing component; medium means a likely interpretation where another configuration is possible; needs-review means information is missing, wording is ambiguous, or the logic isn't supported. The question it answers for a researcher is simply: where should I look most carefully?
Q14 may never appear. Its condition depends on an answer that is unavailable in Q8.
Ready to import
High-confidence mappings, still fully editable — the reviewer confirms rather than rebuilds.
Review recommended
AI found a plausible interpretation but an alternative configuration is defensible.
Action required
Conflicts or missing information that block safe configuration until a person decides.
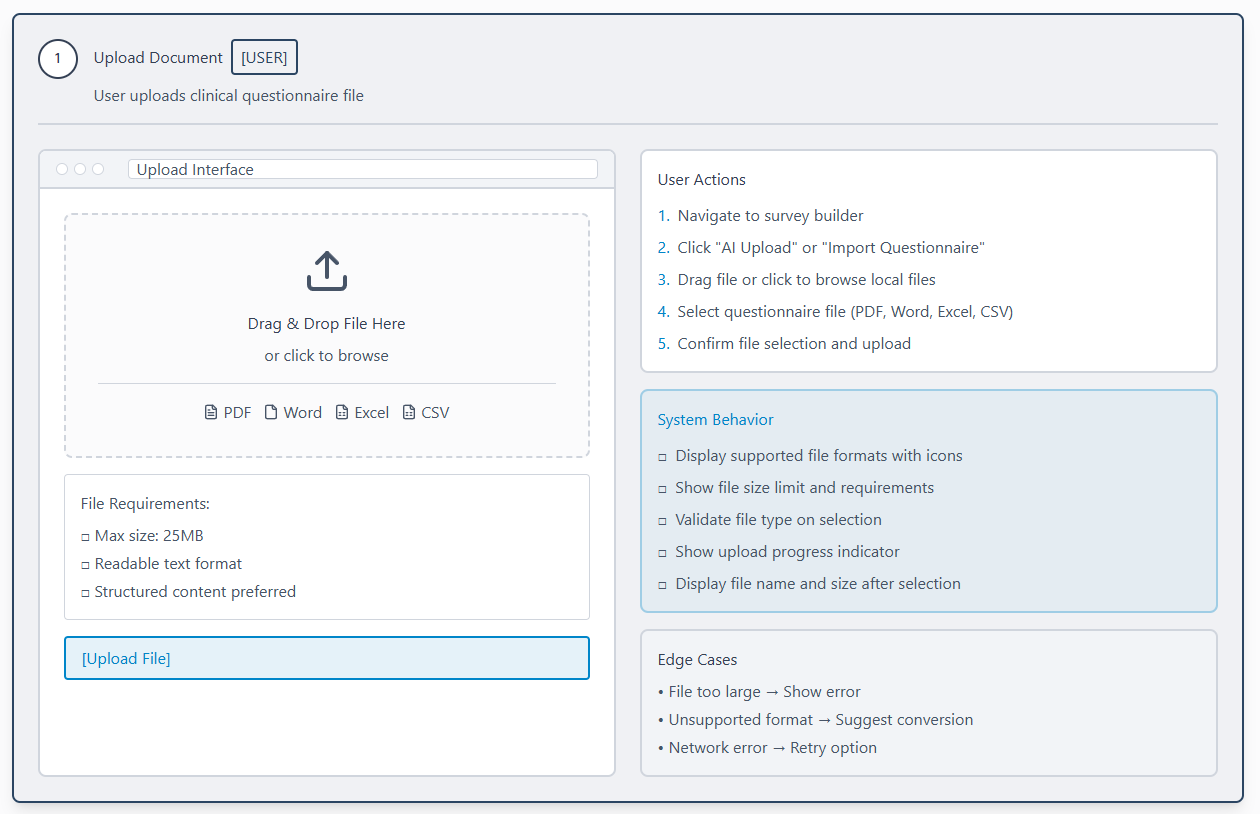
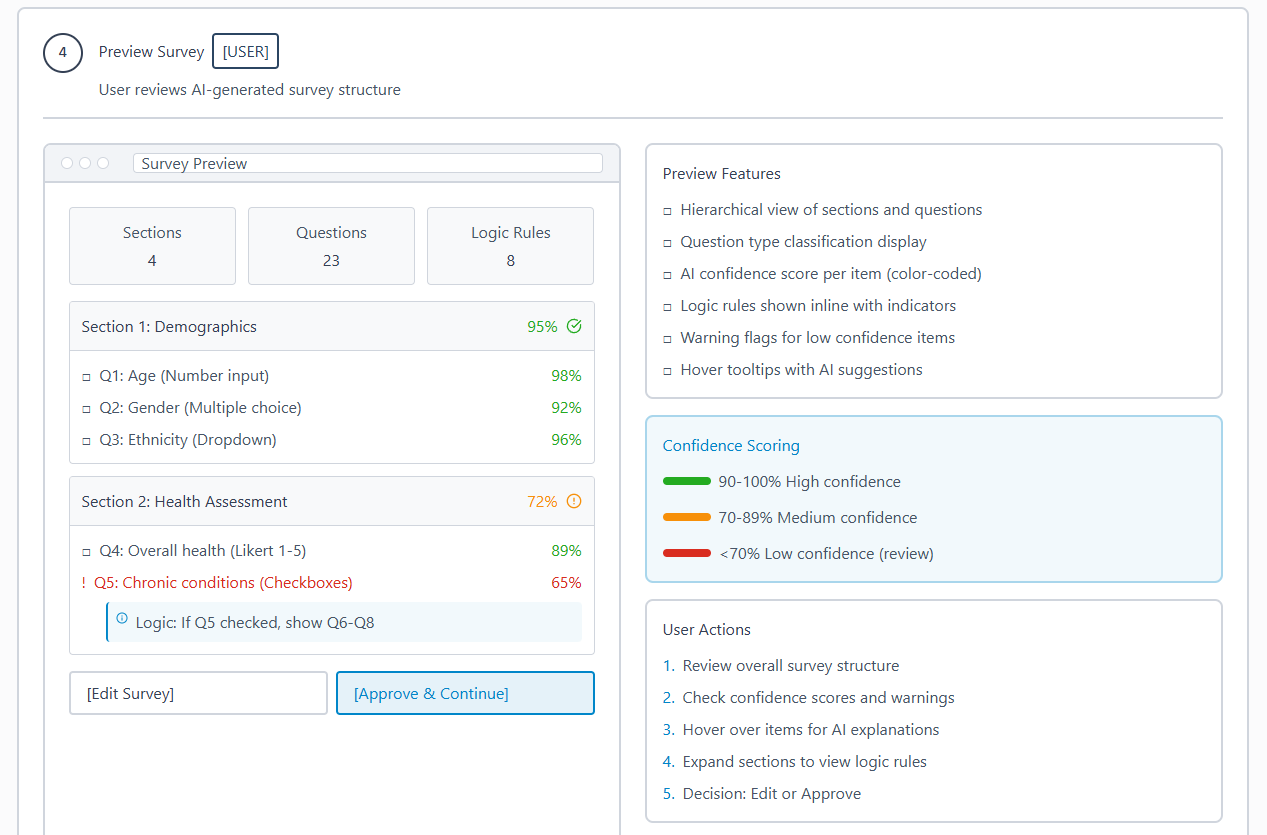
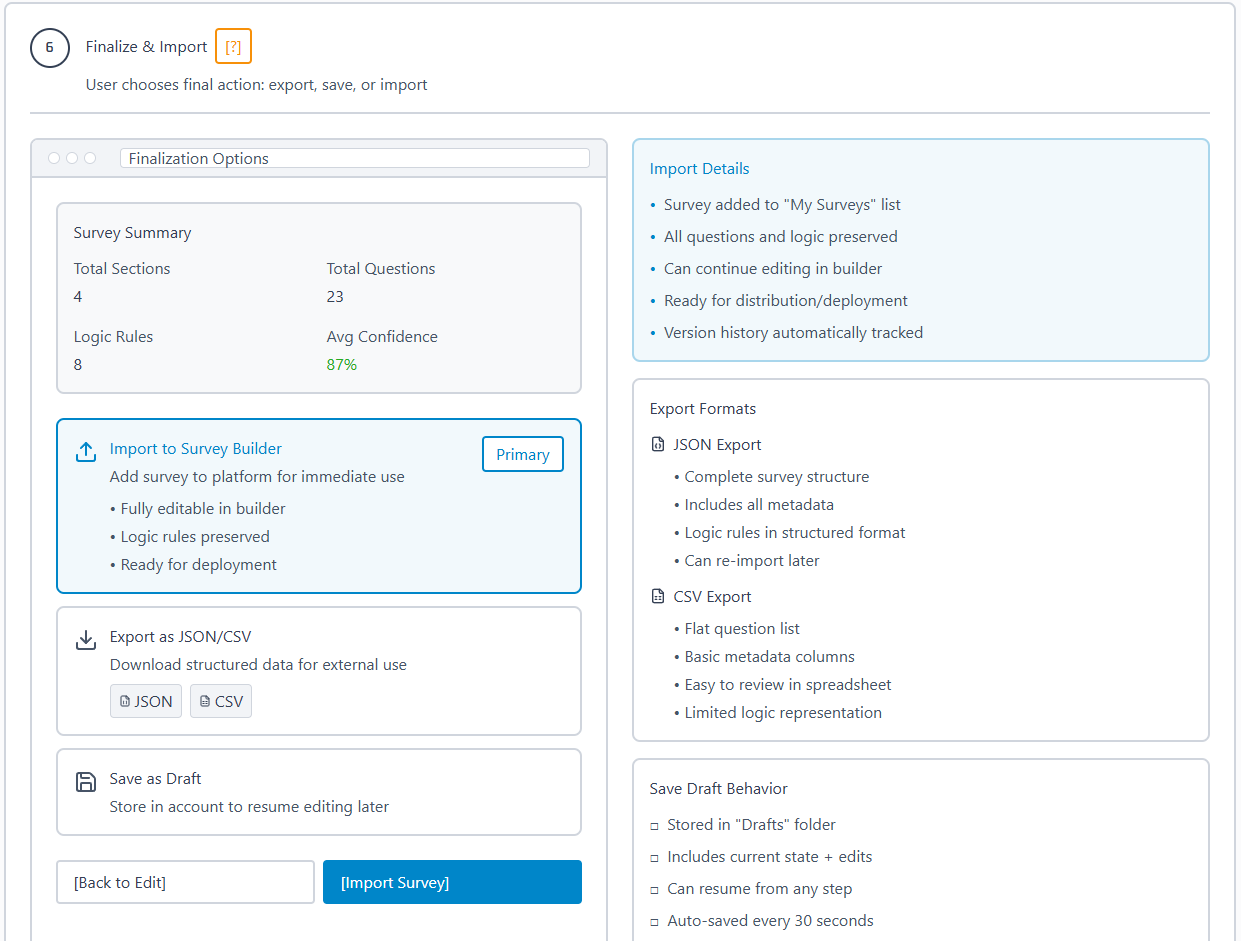
Before import, AI validates the survey as a system rather than question by question — unreachable questions, broken branching paths, duplicate items, conflicting conditions. And approved content enters the same redesigned builder rather than spawning a parallel AI workflow, which was a deliberate architectural call: AI should accelerate the existing product, not become a second product people have to learn. I'd phase it accordingly — extract and classify first, then logic assistance, then whole-survey validation, and only then optional optimization for readability and accessibility.
Reflection
This project reinforced the importance of addressing foundational UX and system limitations before layering AI on top. The redesign shifted how teams think about building surveys — from manual, error-prone steps to a streamlined, modular, feedback-rich workflow. The biggest takeaway was the need for transparent AI, where users can always review, edit, and override suggestions. In clinical environments, accuracy is non-negotiable.
Outcome
Shipped
Phase 1 performance and UX redesign delivered with the dev team.
Validated
100% task completion and 55% faster logic configuration in testing.
On the roadmap
AI-assisted builder concept adopted into the 2026 product roadmap.